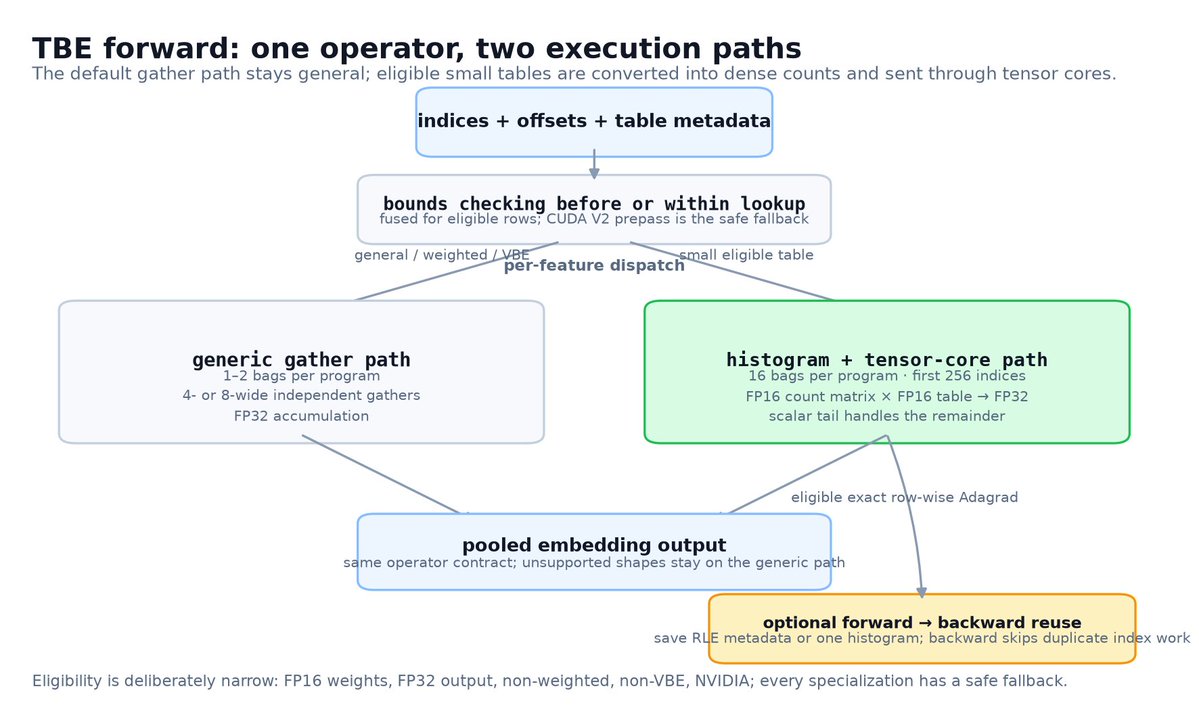
Replacing CUDA with FBTriton for Table Batched Embedding (TBE) kernels delivered massive gains for our rec sys models. @Meta contributors achieved up to 1.28x faster forward passes, 2x faster backward passes, and a huge boost in developer velocity. Check out the engineering