Sparse attention fixes memory bandwidth, not memory capacity. “The whole idea of HiCache is trying to offload KV cache from the HBM to a lower tier, higher capacity but lower bandwidth memory, and only load the most relevant set of tokens during computation.” “Sparse attention
  1. #1

    Video posted by SemiAnalysis (@SemiAnalysis_)

  2. #2

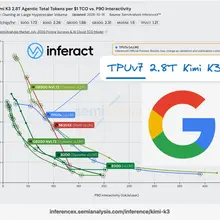
    BREAKING NEWS🚨: @Inferact & Google submit their FIRST preliminary TPUv7 Kimi K3 2.8T Model Submission, and it is already delivering strong perf per TCO against GB200 NVL72, B3…

  3. #3

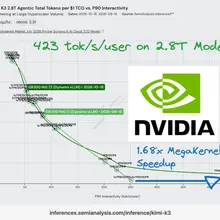
    BREAKING NEWS🚨: NVIDIA has just achieved 423 tok/s/user 🚀 on the 2.8T Parameter Kimi K3 model via a new upstream vLLM optimization. 1.68x Faster on the Same Hardware! This was don…

  4. #4

    GLM 5.3’s biggest leap came from post-training alone. “GLM 5.3 was built entirely by post-training the previous model. For me, that was a wake-up call.” “Post-training is far more…

  5. #5

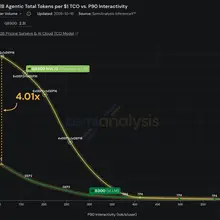
    TOKENMAXXING: @vllm_project and @inferact achieve 1.3 BILLION tokens per $ of TCO (hyperscaler volume pricing) via disaggregated serving on AgentX. This result is 4x better than t…

  6. #6

    MEME: If GPT-7 is AGI, OpenAI could potentially ditch Broadcom entirely and bring everything in-house, as GPT-7 could be better than Broadcom at designing 224G SerDes, handling PD…

查看 @SemiAnalysis_ 的全部帖子