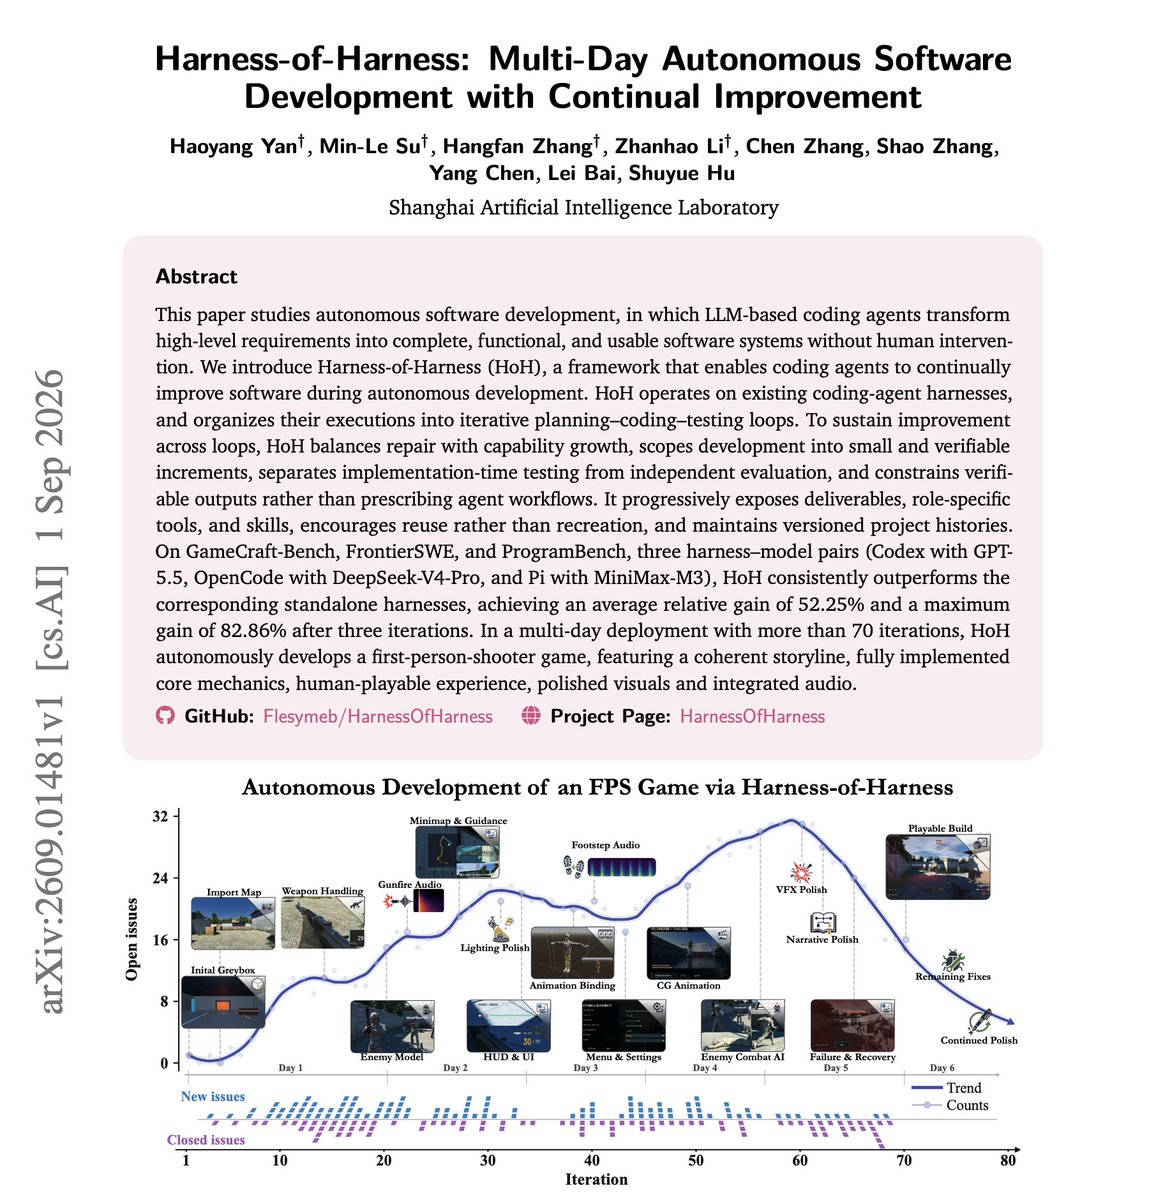
// Harness-of-Harness // Exciting new research on coding agents that keep building for days without a human. Here is how it works: Harness-of-Harness wraps whatever coding harness you already run and organizes its executions into repeated planning, coding and testing
DAIR.AI @dair_ai ·
  1. #1

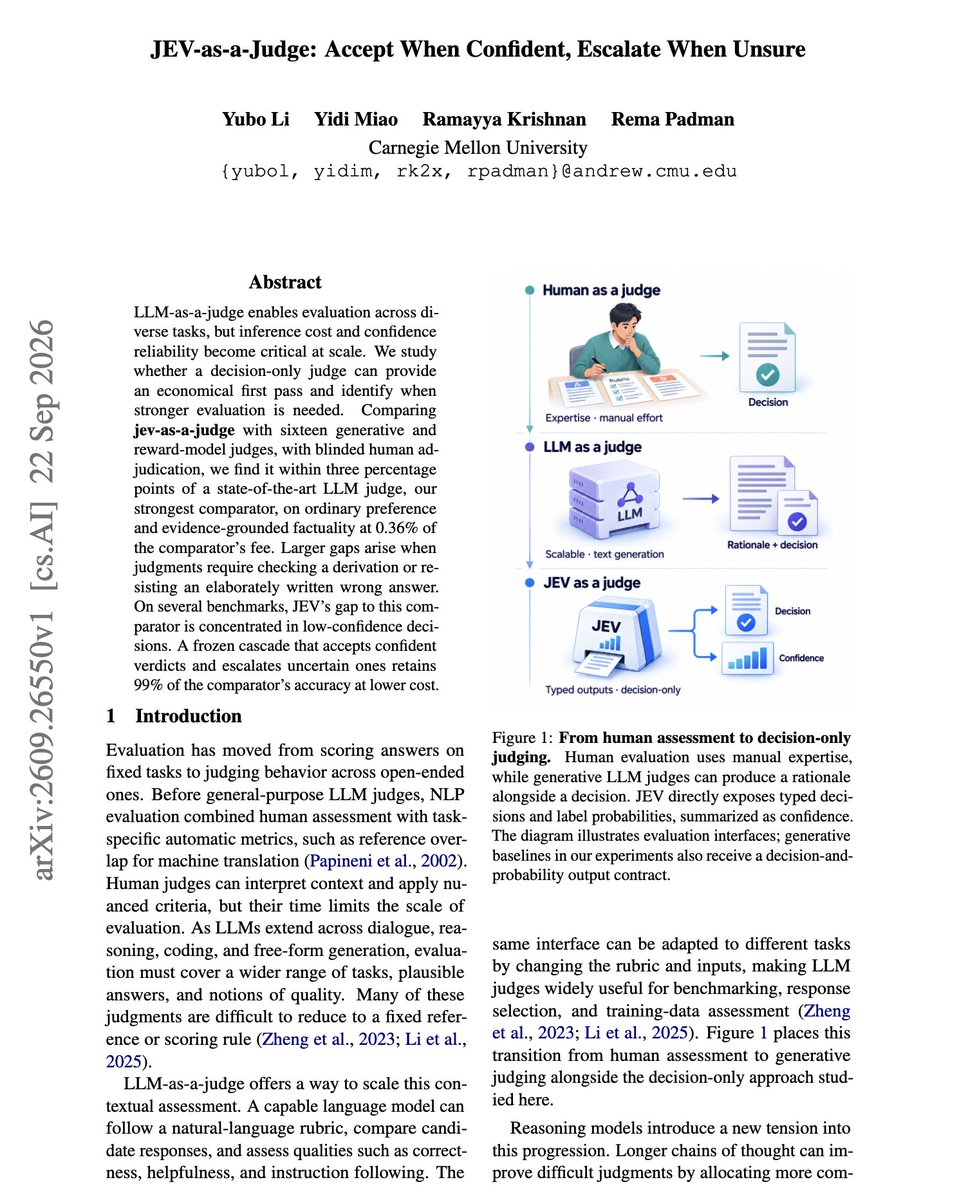
    Banger paper introducing Jev-as-a-Judge. The overall finding is that you want to use a cheap judge for most of your evals and send only the uncertain calls to a frontier model. Th…

  2. #2

    Insightful paper from Microsoft and colleagues. If you have ever had an agent run fail 80 steps ago with no way to find where, this one is for you. (bookmark it) Agent failures sh…

  3. #3

    Brilliant new paper from the Qwen team. It provides insights into where agent training environments actually come from. Terminal agent trajectories have accumulated at scale while…

  4. #4

    Great tips on working with reasoning models. Normally you would append what the model figured out after the document and ask again. It turns out that where you put the reasoning t…

  5. #5

    Brilliant paper on long-horizon agents. They cut 78.9% of an agent's LLM calls while raising its success rate. Here is how: It turns out that ReAct issues one primitive action per…

  6. #6

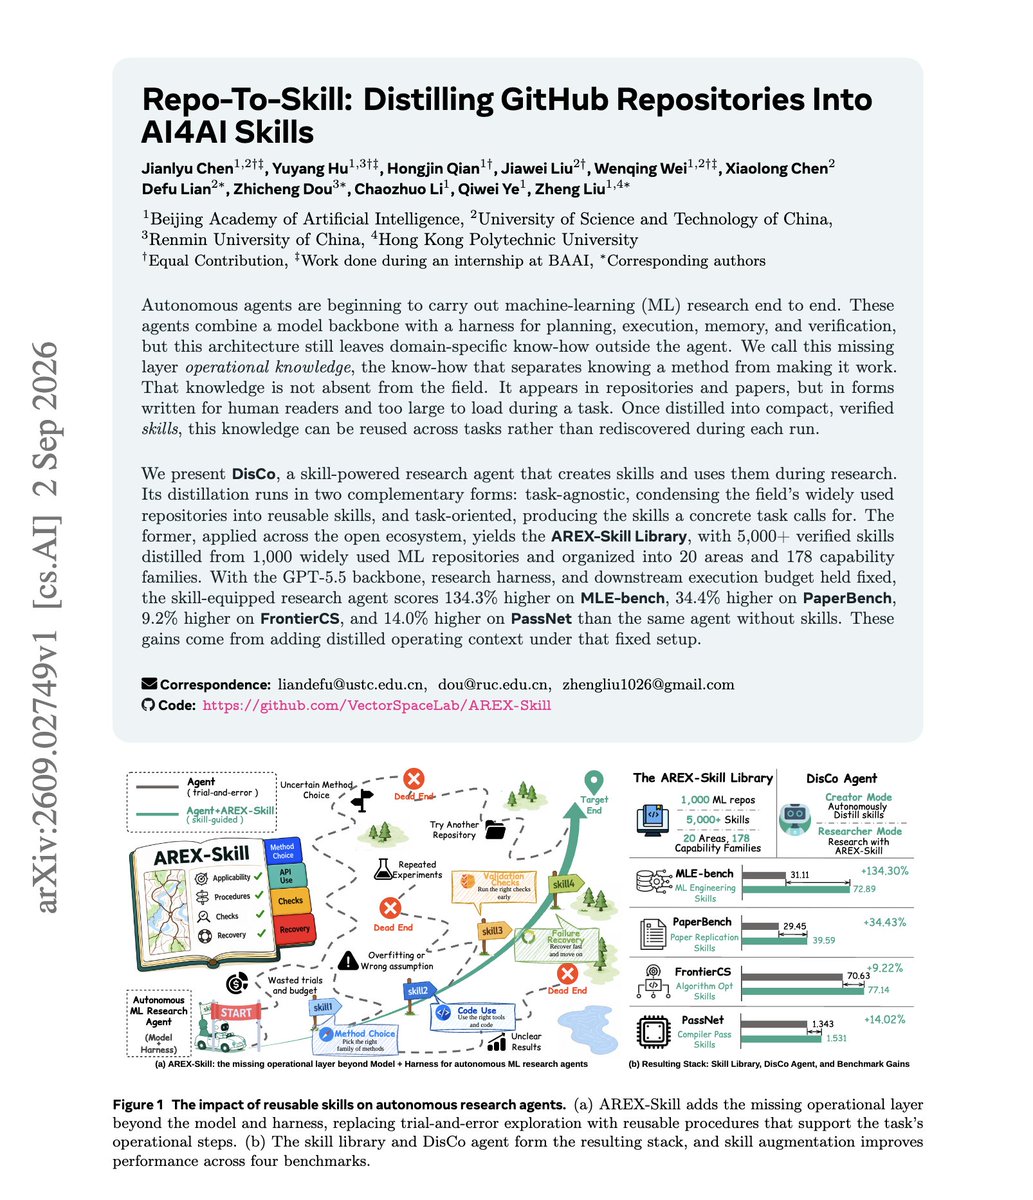
    Banger paper from BAAI. If you are building research agents, this one is worth your time. (bookmark it) They find that adding skills scores 134.3% higher on MLE-bench, 34.4% highe…

查看 @dair_ai 的全部帖子