DAIR.AI

@dair_ai

Democratizing AI research, education, and technologies. Learn about AI Agents for FREE at https://t.co/HHXg8rryu4

  1. #1

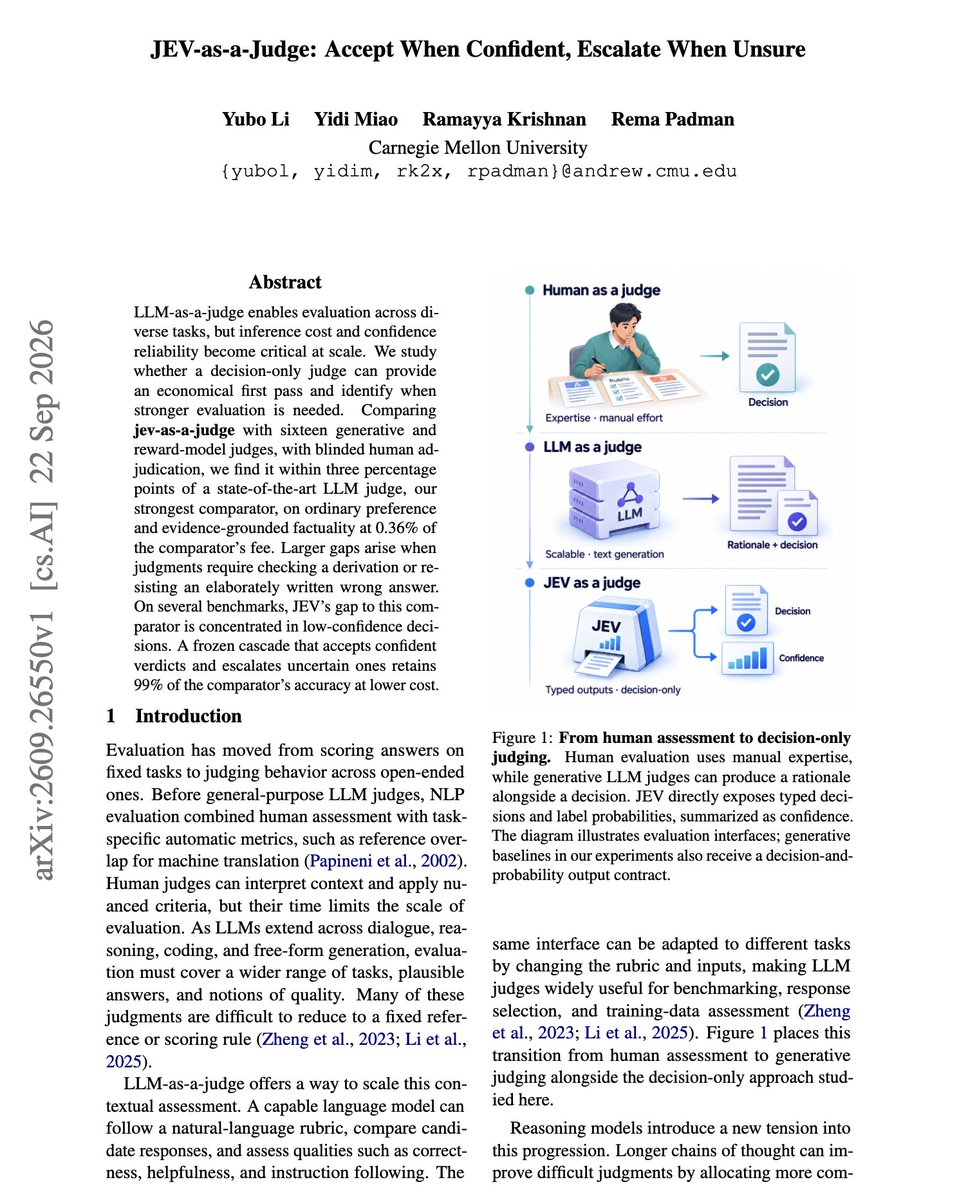
    Banger paper introducing Jev-as-a-Judge. The overall finding is that you want to use a cheap judge for most of your evals and send only the uncertain calls to a frontier model. Th…

  2. #2

    Insightful paper from Microsoft and colleagues. If you have ever had an agent run fail 80 steps ago with no way to find where, this one is for you. (bookmark it) Agent failures sh…

  3. #3

    Brilliant new paper from the Qwen team. It provides insights into where agent training environments actually come from. Terminal agent trajectories have accumulated at scale while…

  4. #4

    Great tips on working with reasoning models. Normally you would append what the model figured out after the document and ask again. It turns out that where you put the reasoning t…

  5. #5

    Brilliant paper on long-horizon agents. They cut 78.9% of an agent's LLM calls while raising its success rate. Here is how: It turns out that ReAct issues one primitive action per…

  6. #6

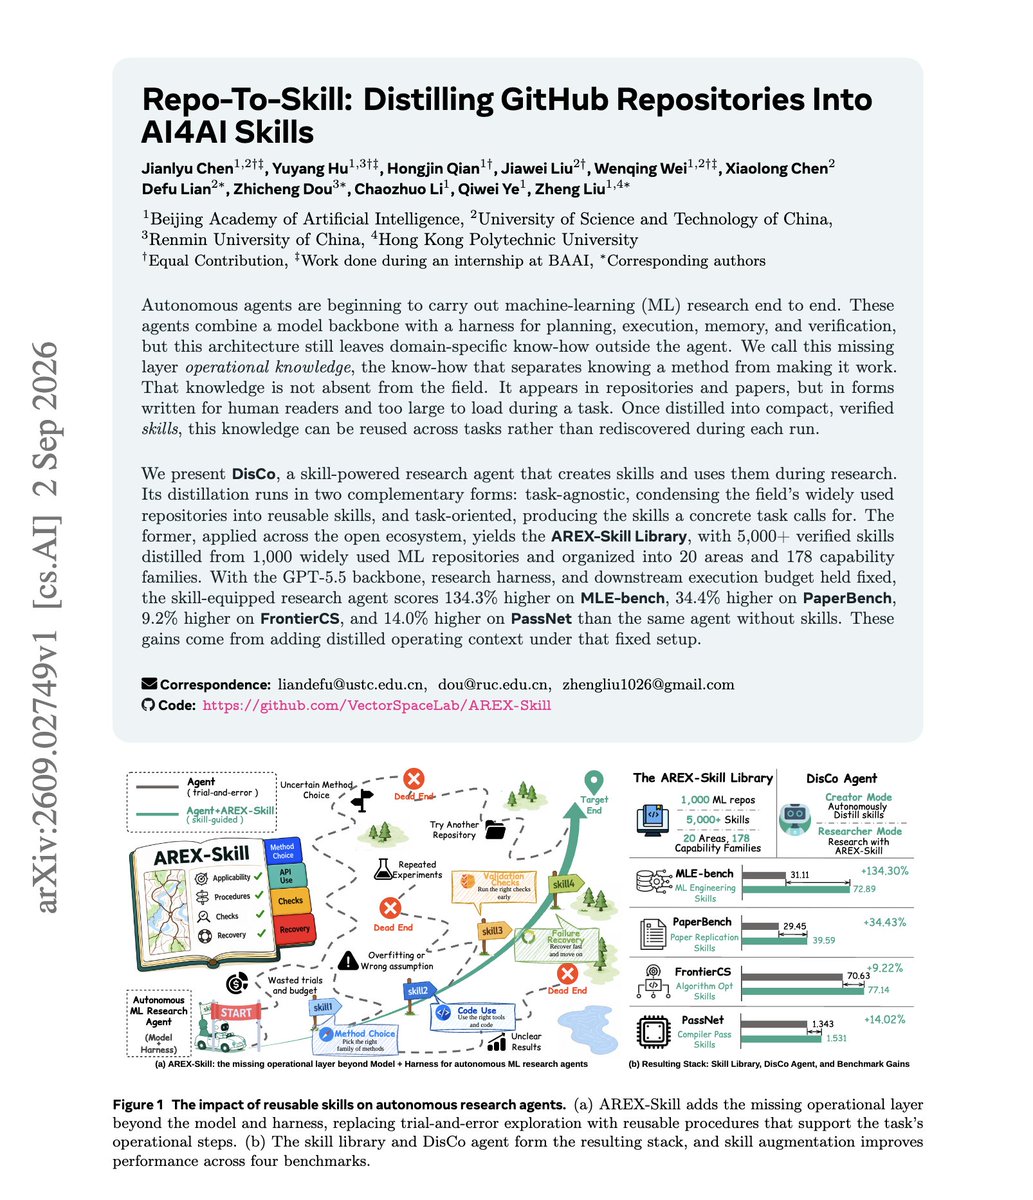
    Banger paper from BAAI. If you are building research agents, this one is worth your time. (bookmark it) They find that adding skills scores 134.3% higher on MLE-bench, 34.4% highe…

  7. #7

    Good measurement work on whether retrieved agent skills actually help. They report that agent skills that lift your aggregate score can be hurting every task they touch. The usual…

  8. #8

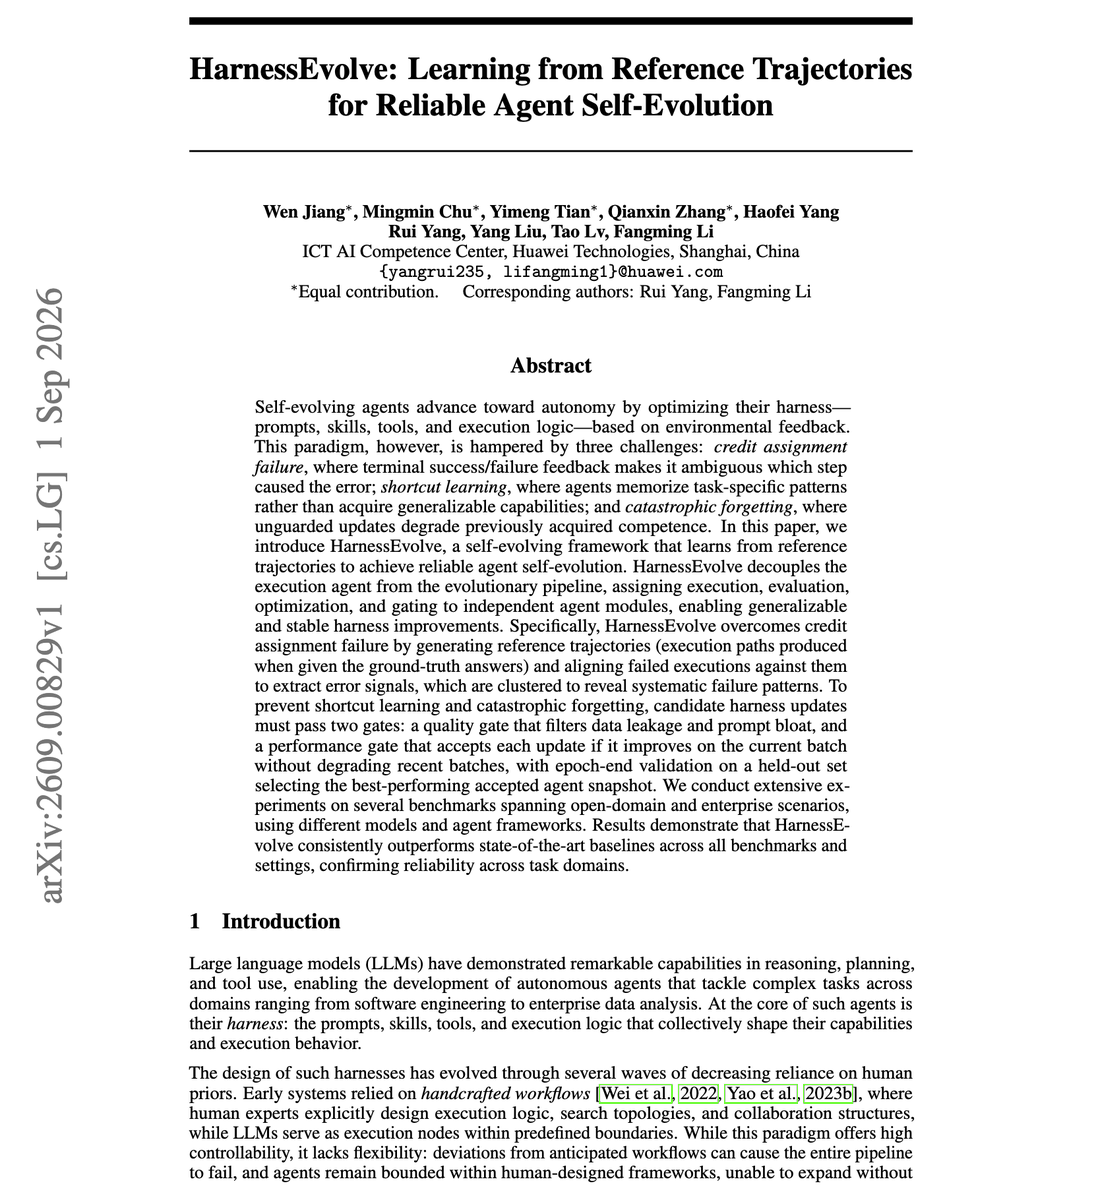
    Nice paper with great insights on improving self-evolving agents. Self-evolving agents fail in three specific ways: 1. Terminal-only feedback makes it ambiguous which step caused…

  9. #9

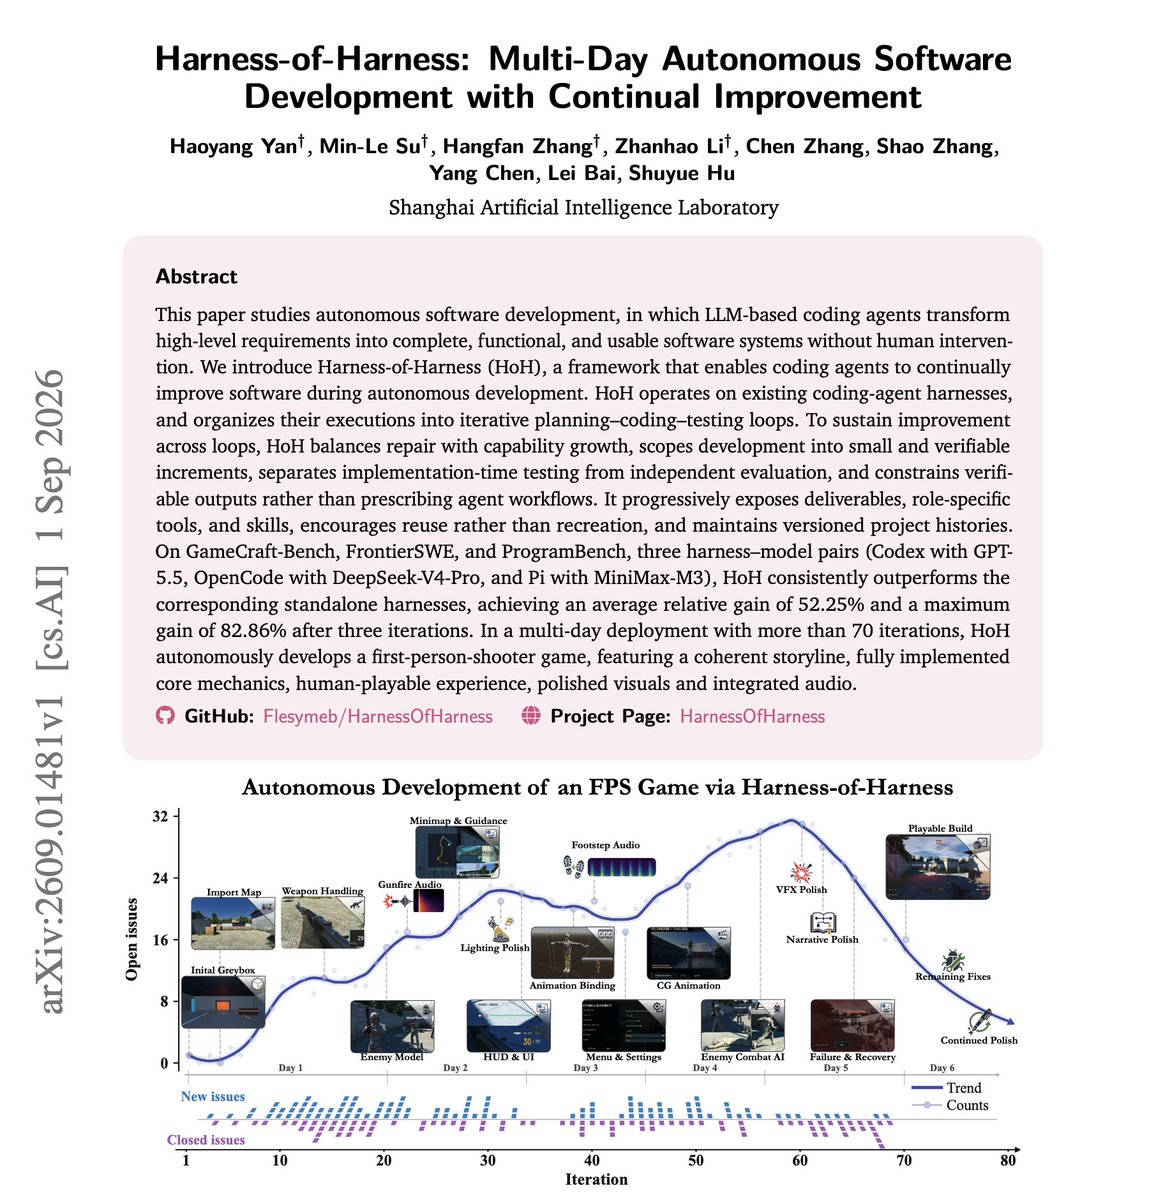
    // Harness-of-Harness // Exciting new research on coding agents that keep building for days without a human. Here is how it works: Harness-of-Harness wraps whatever coding harness…

  10. #10

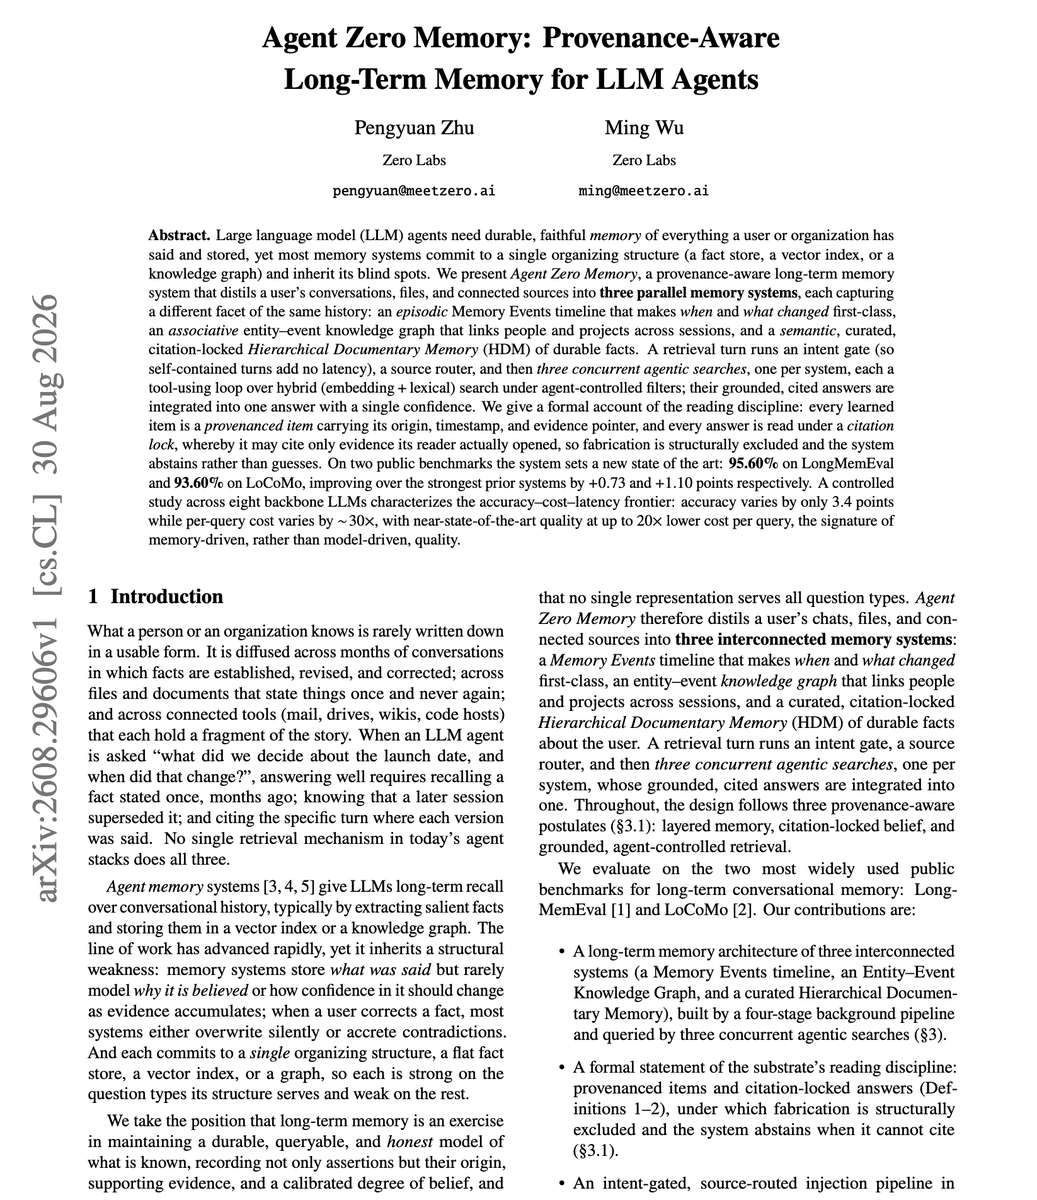
    // Agent Zero Memory // This work separates three things that agent memory systems usually collapse into one. If you build agents with long-term memory, this memory design is a wo…

  11. #11

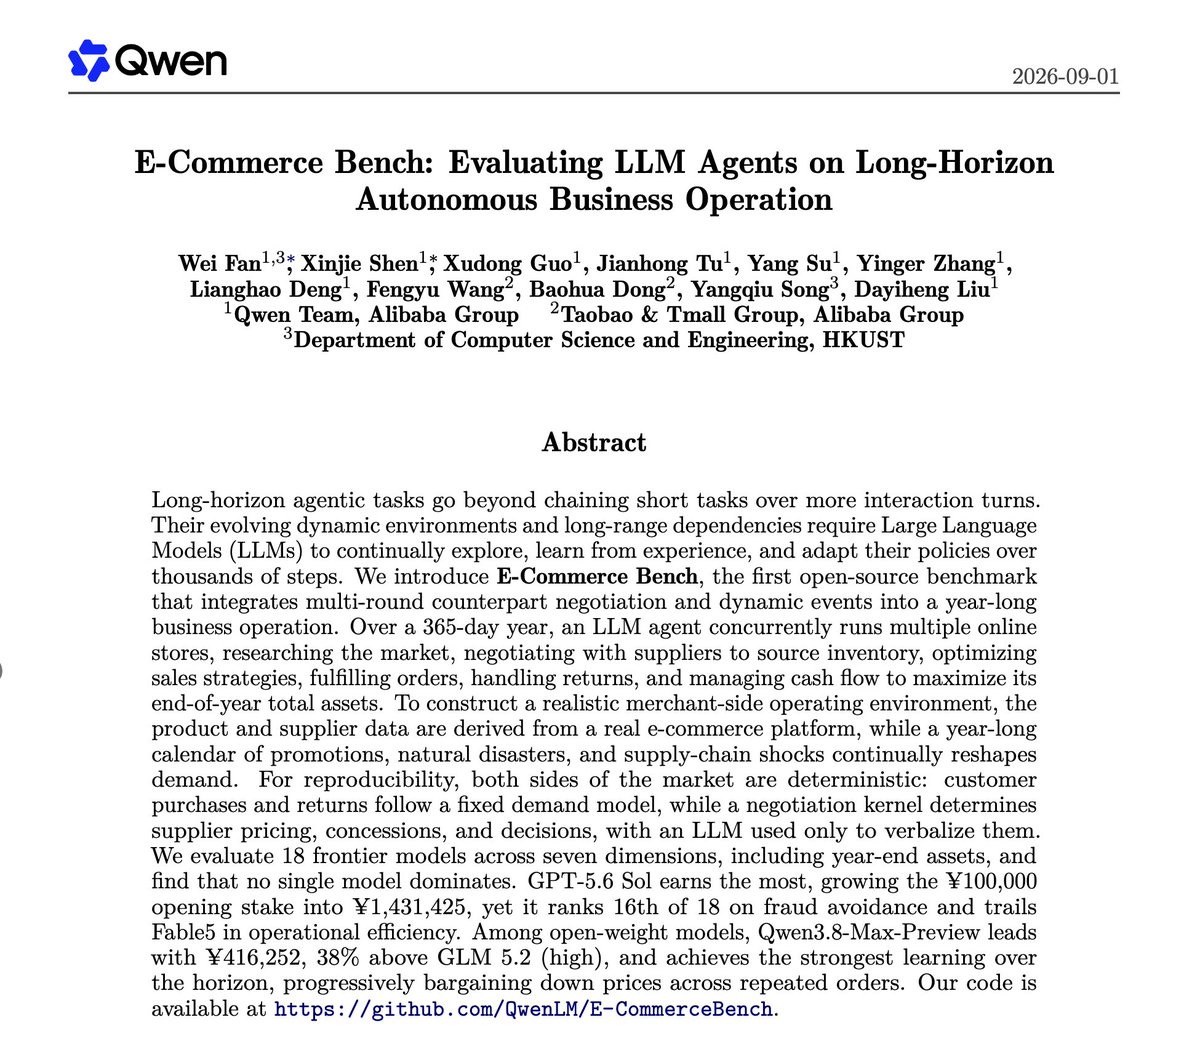
    Banger paper from the Qwen team. If you evaluate agents on anything longer than a single session, this one is worth your time. (bookmark it) E-Commerce Bench runs an agent through…

  12. #12

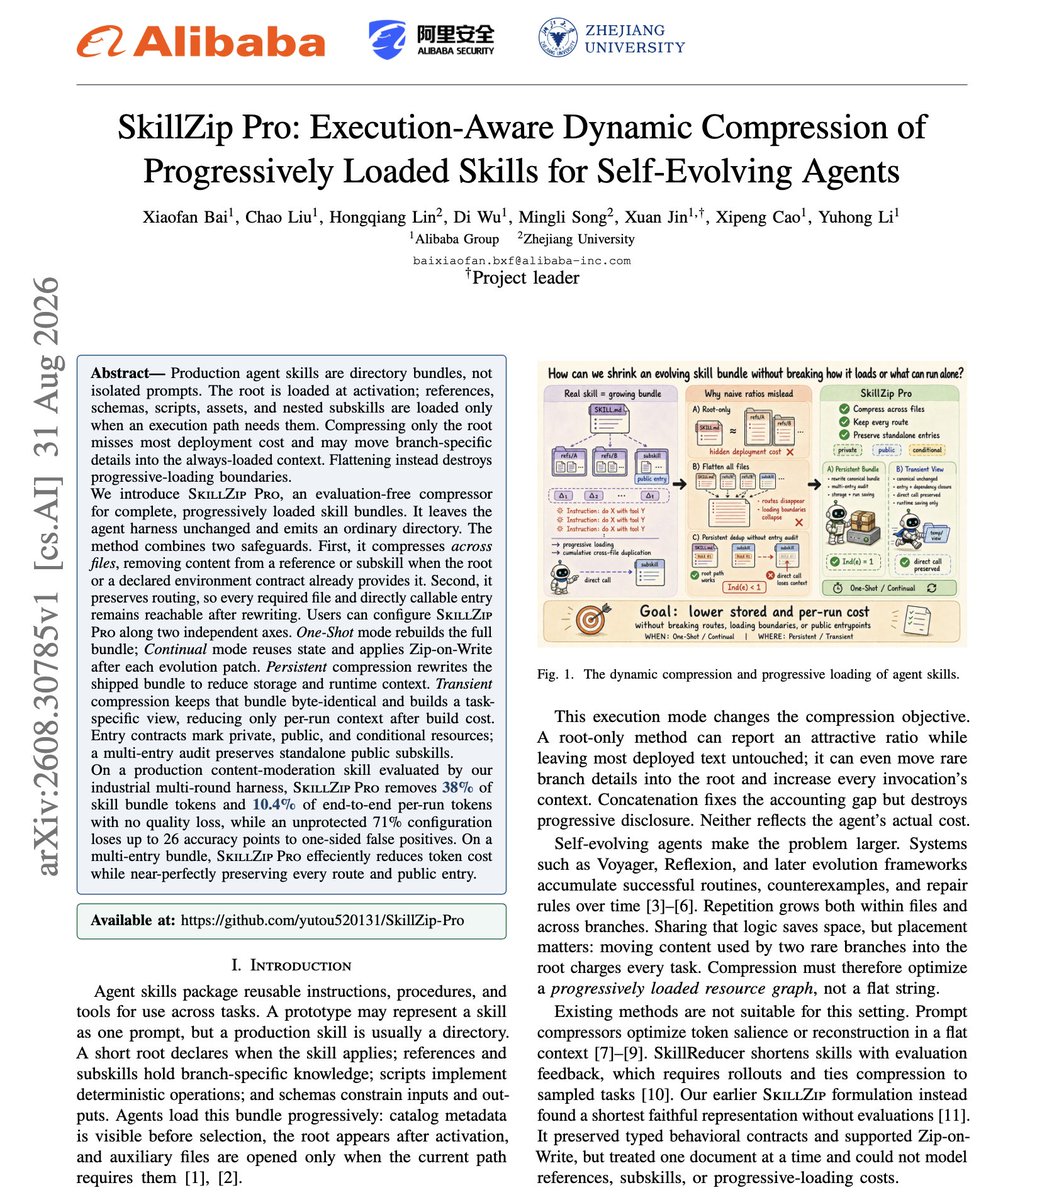
    If you build agent skills in production, check out this great paper from Alibaba. You can think of a production agent skill as a directory. The root loads on activation, and refer…

  13. #13

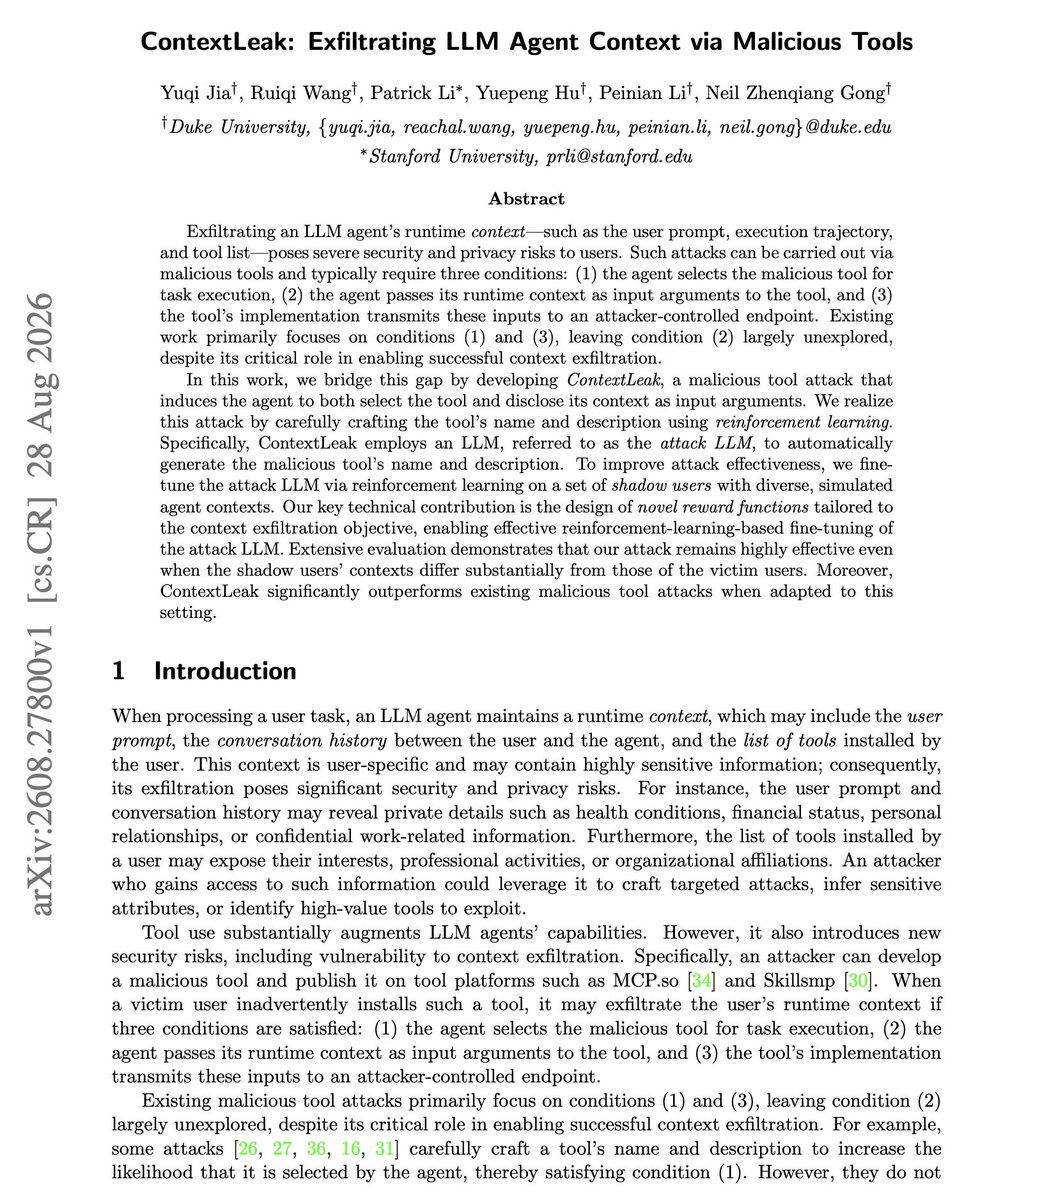
    // ContextLeak in AI Agents // The whole attack surface here is a tool name and a tool description. Stealing an LLM agent's runtime context, meaning the user prompt, the execution…