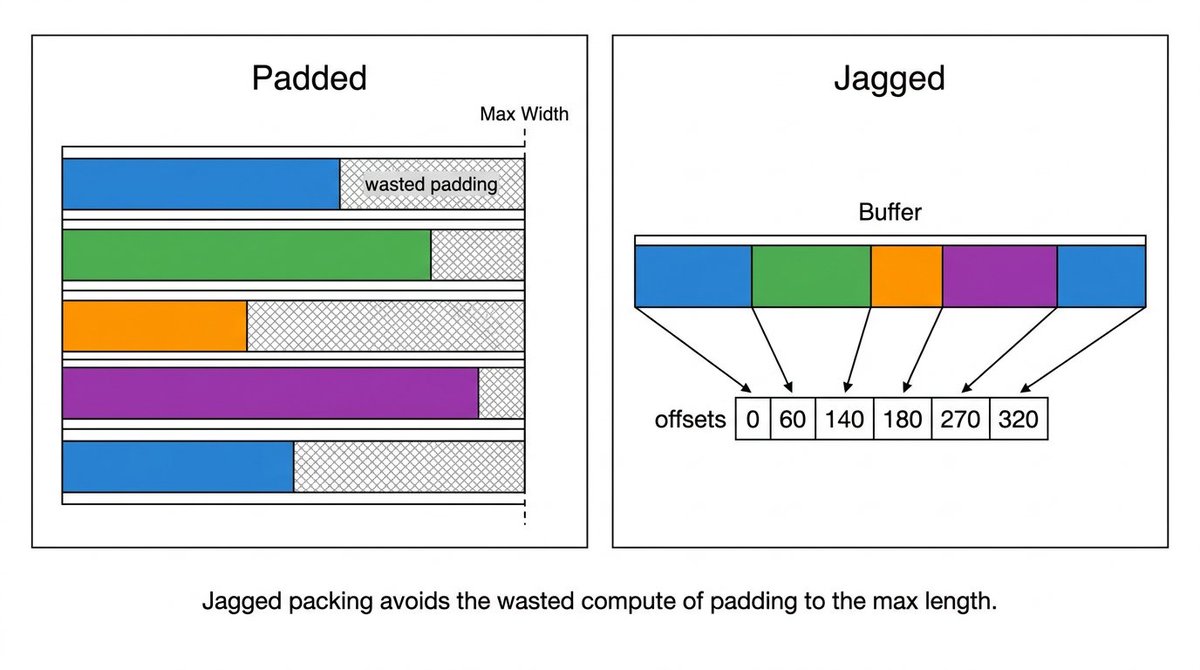
Our latest blog presents work on Jagged Flash Attention (JFA) — the attention kernel behind @Meta's Generative Ads Model (GEM) — on @NVIDIA Blackwell (B200), built with TLX (Triton Low-level Extensions), which add explicit, hardware-aware control on top of Triton's high-level,
PyTorch @PyTorch ·
  1. #1

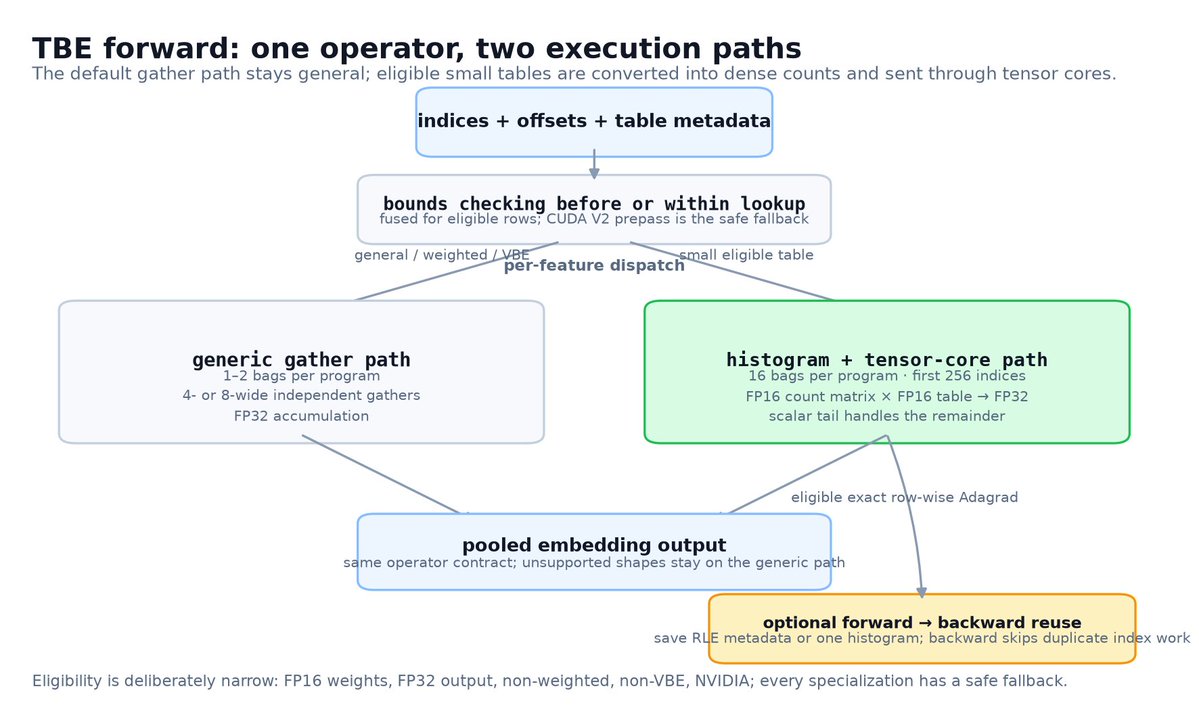
    Replacing CUDA with FBTriton for Table Batched Embedding (TBE) kernels delivered massive gains for our rec sys models. @Meta contributors achieved up to 1.28x faster forward passe…

  2. #2

    Think @DeepSpeedAI is only good for ZeRO and its usability, not training throughput? At #PyTorchCon North America 2026, Masahiro Tanaka will cover tensor, sequence, and expert par…

  3. #3

    October 19: @RedHat, @NVIDIA AI, and @IBM are hosting “PyTorch, Powering the Enterprise,” a #PyTorchCon North America Day 0 event. The in-person event will explore PyTorch and the…

  4. #4

    From torch.profiler to Hardware Cycles: A Practical Profiling Playbook AWS Trainium: designed from the ground up for next generation AI training and inference is now a standard Py…

  5. #5

    The #OpenSourceAIWeek lineup is loading. Is your event on it? ⏳ Join the Bay Area celebration, October 16-25, with flagship events #PyTorchCon North America, October 20-21, and #A…

  6. #6

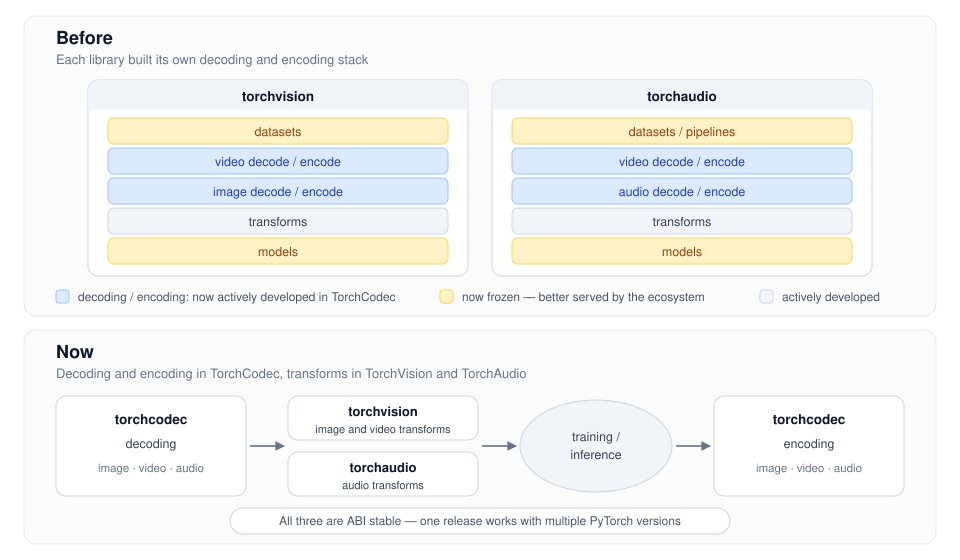
    Over the last two years, @Meta has consolidated PyTorch's media stack across three libraries: TorchCodec, TorchVision, and TorchAudio. TorchCodec serves as the single home for CPU…

查看 @PyTorch 的全部帖子